
Table of Contents
Your application may work perfectly with 100 users and still struggle at 1,000. The problem isn’t always the server. A database query, connection pool, synchronous API call, background job, or deployment process can become a bottleneck.
Before ramping up your traffic, customers, or infrastructure, use a technical scalability checklist to discover what to scale, what to optimize, and what will break.
Quick Answer: Is Your System Ready to Scale?
A system is better equipped to scale when you know what load it is expected to handle, the potential performance bottlenecks, database limitations, API requirements, background processing features, infrastructure requirements, monitoring tools, deployment rollback procedures, security measures, recovery procedures, and expected costs. BkAbhi helps startups approach these technical considerations with a practical focus on building scalable digital products from the start.
Don’t treat “scaling” as simply adding more servers.
First establish how the application behaves as workload increases. Then test the critical paths under realistic conditions and fix the bottlenecks that appear.
What Does Technical Scalability Mean?
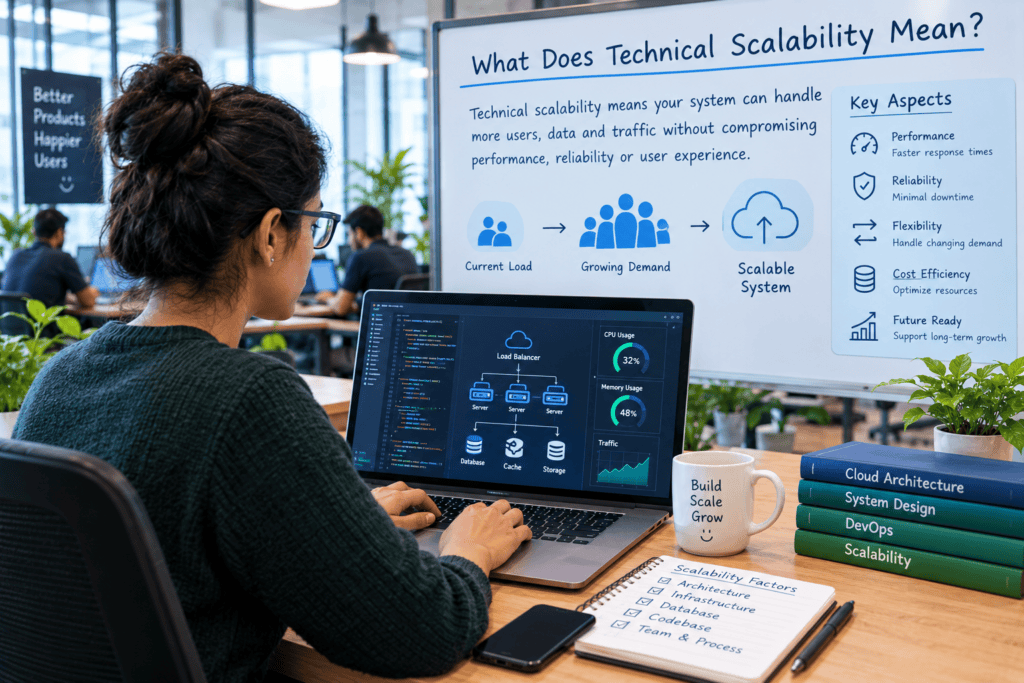
Technical scalability is the ability of a software system to accommodate increased workload without unacceptable degradation in performance, reliability, security, or operating cost.
Workload can grow in several ways:
- More simultaneous users
- More API requests
- More transactions
- Larger databases
- More files or media
- More background jobs
- More tenants in a SaaS platform
- More third-party integrations
- More AI or data-processing requests
There isn’t one universal scalability threshold.
A SaaS application handling thousands of short requests has different requirements from a data-processing platform handling a smaller number of CPU-intensive jobs.
That is why the first step is to define the growth scenario you’re preparing for.
Technical Scalability Checklist Before Scaling
Define the Growth Scenario
Don’t start with “we need to support 100,000 users.”
Start with the workload those users create.
Document:
- Current daily active users
- Expected peak concurrent users
- Requests per second
- Transactions per minute
- Database growth
- File or object-storage growth
- Background jobs per minute
- Expected geographic distribution
- Traffic spikes
- API calls to external providers
For example, a SaaS product might currently have 500 active users but only 20 concurrent users.
If a marketing campaign is expected to create 200 concurrent sessions, that is a much more useful scaling target than the total registered-user count.
Your scaling target should describe the workload the system actually has to process.
Map the Architecture and Critical Paths
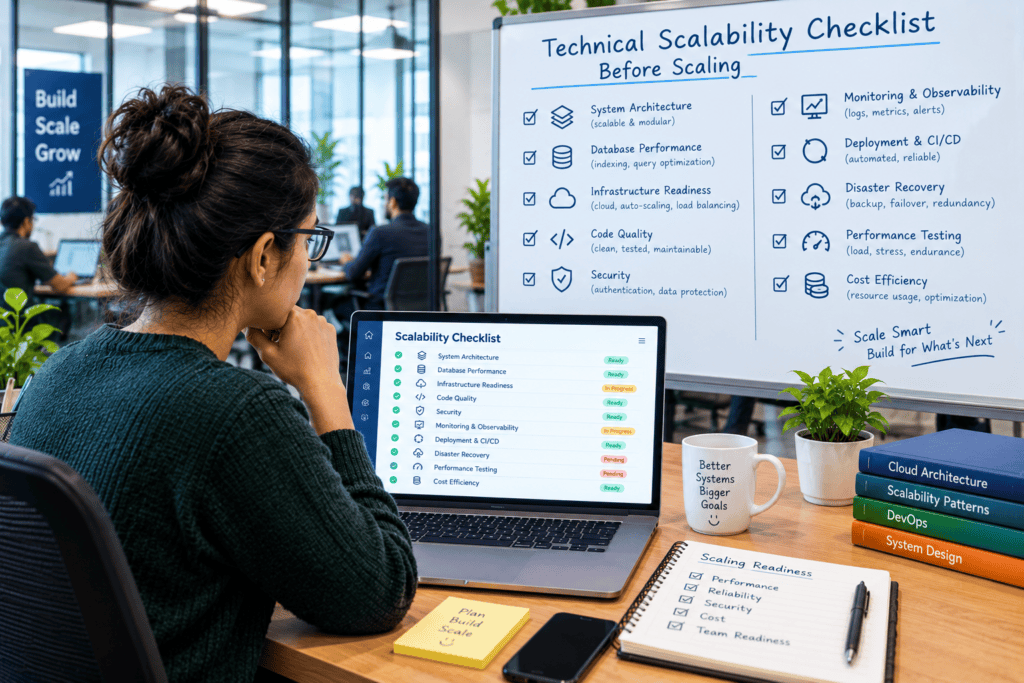
Before optimizing anything, map the request path.
A simple SaaS scenario could look like this:
User → CDN/load balancer → application server → API → database → external service
Or maybe something like:
User → API → queue → worker → database → notification service
The point is not to come up with some beautiful architecture diagram.
The point is to understand what is a single point of failure for the whole scenario.
Look for:
- Single application servers
- Shared databases
- Shared caches
- Centralized queues
- Single workers
- Synchronous third-party calls
- Shared storage
- Scheduled jobs
- Global locks
- Single points of failure
AWS’s Well-Architected guidance treats architecture decisions as trade-offs across operational excellence, security, reliability, performance efficiency, cost optimization, and sustainability. That bigger picture is valuable, because a system that can scale well but can’t be safely deployed or recovered from isn’t really ready for scaling up. KeyCDN’s guidance on scalability testing also highlights the importance of evaluating how systems perform as workloads increase.
Identify the Current Bottleneck
Don’t optimize every component before you know what is limiting the system.
Measure:
- CPU utilization
- Memory utilization
- Disk I/O
- Network traffic
- Request latency
- Error rates
- Database latency
- Database connections
- Queue depth
- Worker utilization
- Cache hit rate
- External API latency
The objective is to determine where the performance begins to degrade under a rising workload.
For example:
Scenario A: CPU reaches its limit first.
There is a need to scale up the amount of computing or to optimize the applications’ processing.
Scenario B: Database latency increases while CPU of applications is low.
Adding more application servers may accomplish very little.
Scenario C: Latency of an external API is a dominant force.
Scaling up the server would not resolve the issue.
Increasing your own server capacity won’t solve the underlying problem.
This is one of the most important principles in a technical scalability checklist: scale the bottleneck, not the component that’s easiest to upgrade.
Review Compute and Infrastructure Capacity
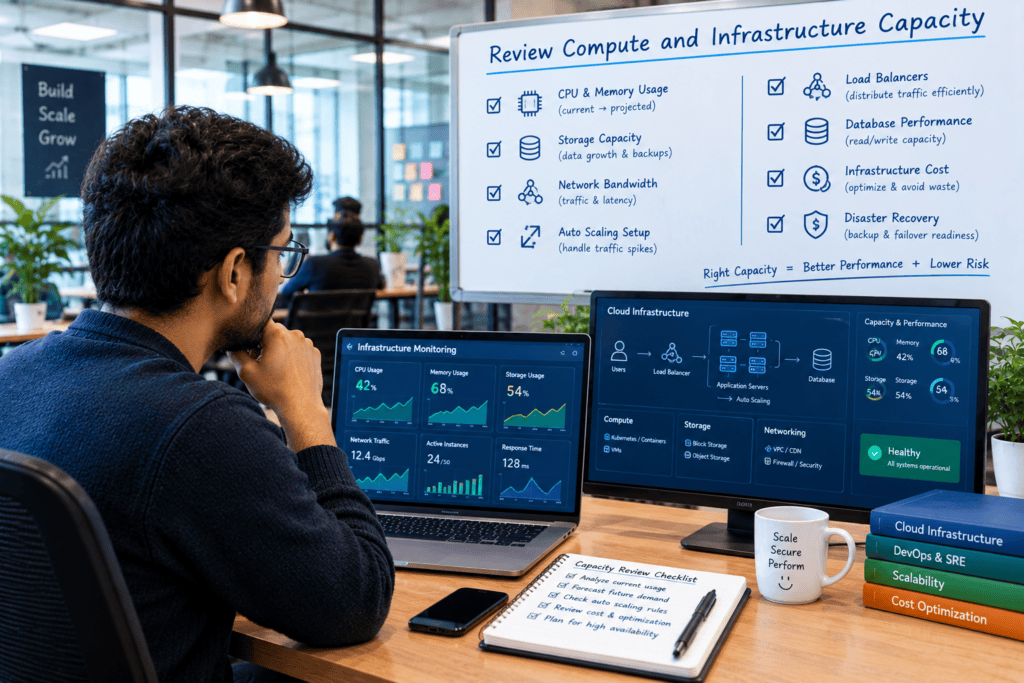
Check whether your current infrastructure has enough headroom for expected demand.
Review:
- CPU
- Memory
- Disk capacity
- Network throughput
- Instance/container limits
- Autoscaling configuration
- Load balancing
- Health checks
- Availability zones or equivalent redundancy
- Resource limits and requests
- Startup and shutdown behavior
Vertical scaling means increasing the resources available to an existing machine or workload.
Horizontal scaling is a method of adding instances or replicas
Both approaches can be appropriate in certain cases.
For example, moving to a larger server may be sufficient for a modest increase in demand. A workload which requires multiple application instances would benefit from using horizontal scaling as a different approach.
AWS documents autoscaling as a way to add capacity for peak demand and remove capacity when demand decreases. Kubernetes has a Horizontal Pod Autoscaler that scales the capacity of a workload based on metrics it observes.
The important question isn’t “Which scaling method is better?”
Which method fits the workload, architecture, reliability requirements, and budget?
Check Database Scalability
The database is often where scaling problems become expensive.
Review:
- Slow queries
- Missing indexes
- Inefficient joins
- Large result sets
- Connection limits
- Connection pooling
- Lock contention
- Transaction duration
- Read/write patterns
- Storage growth
- Backup duration
- Replication behavior
- Data retention
- Archiving strategy
For PostgreSQL, tools such as EXPLAIN and EXPLAIN ANALYZE can help investigate query execution behavior.
Don’t automatically assume that a larger database server is the answer.
If one query is performing a full-table scan unnecessarily, adding hardware may only postpone the problem.
For document databases such as MongoDB, horizontal scaling through sharding can distribute data and workload across multiple machines, but it introduces additional infrastructure and operational considerations.
Database scaling should therefore start with measurement and query behavior, not with an assumption that the database needs to be replaced or sharded.
Review API Scalability
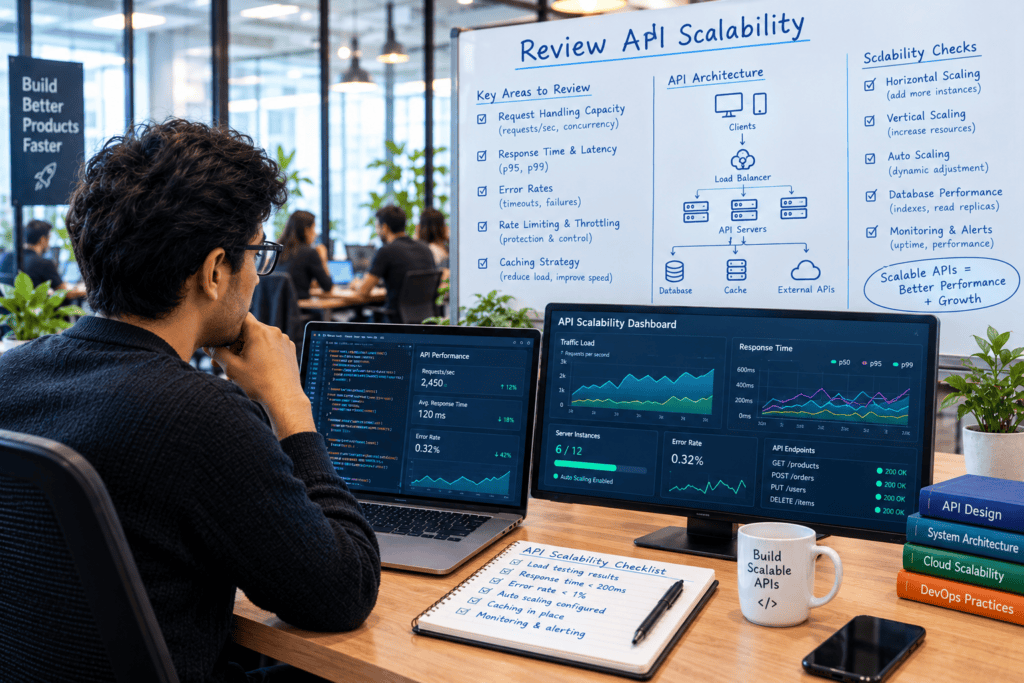
Your API needs to remain predictable as traffic increases.
Check:
- Requests per second
- Response latency
- Time out
- Rate limits
- Authentication overhead
- Payload size
- Pagination
- API versioning
- Retry behavior
- Idempotency
- Error handling
- Connection management
Pagination is particularly important if the endpoint is expected to return a large amount of data..
An API that works with 100 records may become expensive when a customer has 100,000.
Similarly, retries can create issues if an operation is not designed to allow retries safely.
Stripe’s API docs give a good example of an idempotency key, which allows a request to be safely retried without accidentally creating two identical operations.
This can be very important for payment, order, provisioning, and other state-changing operations.
Separate Slow Work With Queues
Not every task should happen during the user’s request.
Examples of work that may be suitable for asynchronous processing include:
- Sending large email batches
- Generating reports
- Processing uploaded files
- Image or video processing
- Data imports
- AI processing
- Notifications
- Analytics aggregation
- Synchronizing external systems
Instead of:
User → API → expensive task → response
consider:
User → API → queue → worker → result
This allows the application to return quickly while workers process the longer operation.
But adding a queue isn’t automatically a scalability solution.
Check:
- Queue depth
- Worker capacity
- Retry policy
- Dead-letter handling
- Duplicate processing
- Job visibility
- Failure recovery
- Processing time
An ever-growing queue is not a sign of a scalable system.
Review Caching and Content Delivery
Caching can reduce repeated computation and database load.
- Potential candidates for caching include:
- heavily used data sets
- product catalogs
- configuration
- public data
- expensive computations
- API responses, when appropriate
- static assets
- But you have to ask yourself:
- how long should I cache data for?
- What invalidates it?
- Can stale information cause a business problem?
- What happens when the cache is unavailable?
- Is the cache becoming a new bottleneck?
For static and globally distributed content, a CDN can reduce the amount of traffic reaching the origin application.
The goal isn’t “cache everything.”
The goal is to reduce repeated work where the consistency and invalidation requirements allow it.
Test Third-Party Integrations
A system rarely operates alone.
Your application may depend on:
- Payment providers
- Email services
- Authentication providers
- AI APIs
- CRM systems
- Analytics platforms
- Shipping providers
- Cloud storage
- Webhooks
- External data providers
For every important integration, ask:
What happens if the provider is slow?
What happens if it returns an error?
What happens if it is temporarily unavailable?
Can the request be retried safely?
Can the user continue without it?
Is there a rate limit?
This is especially important for AI powered applications, where relying on a model API introduces latency, billing problems, rate limits and concurrency issues.
Establish Observability Before Scaling
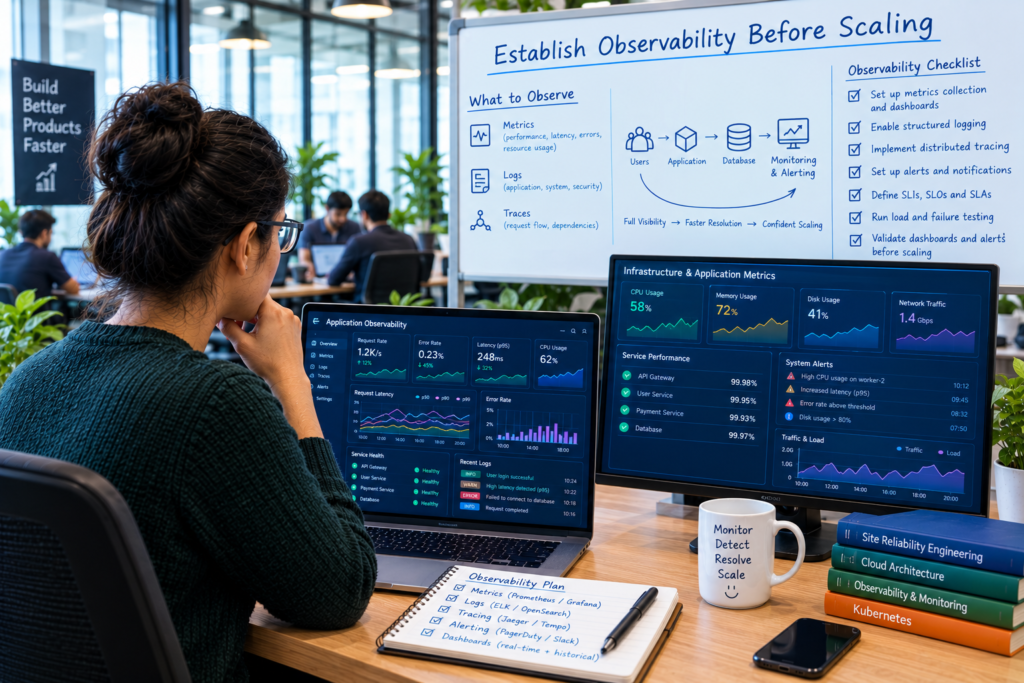
You shouldn’t scale a system you can’t see.
At minimum, identify the metrics that tell you:
- Is the application healthy?
- Are requests getting slower?
- Are errors increasing?
- Is the database overloaded?
- Are queues growing?
- Are external services failing?
- Are users getting worse performance?
Observability commonly combines:
- Metrics
- Logs
- Traces
OpenTelemetry describes itself as a vendor-neutral framework for generating, collecting, and exporting telemetry such as traces, metrics, and logs.
The exact tooling can vary.
The important requirement is that engineers can move from:
“Users say the application is slow.”
to:
“The checkout endpoint’s latency increased because database query X is consuming most of the request time.”
That difference dramatically improves your incident response capability.
Create Actionable Alerts
Without alerts, your team’s monitoring efforts can amount to just sitting and watching the dashboard.
Alerts should be created for significant failure conditions.
Examples might include,
- Error rate is over a given threshold
- Database connections nearing capacity
- Ever-increasing queue depth
- Storage nearing capacity
- Latency on key endpoints is high
- Worker failures
- Certificate about to expire
- Deployments failing
- Backups failing
- Don’t create alerts for every little hiccup.
A useful alert should answer:
What happened, how serious is it, and what should the team investigate?
Validate CI/CD and Rollback
Scaling increases the cost of deployment mistakes.
Before increasing traffic, verify that your deployment process can:
- Build automatically
- Run automated tests
- Deploy consistently
- Track versions
- Detect failures
- Roll back safely
GitHub Actions, for example, supports continuous deployment workflows that can build and test code before deployment.
For higher risk systems consider the following:
- staged deployments
- canary releases
- feature flags
- automated health checks
- database migration safeguards
- rollback procedures
A scalable application with an unsafe deployment process is still operationally fragile.
Review Security and Multi-Tenant Isolation
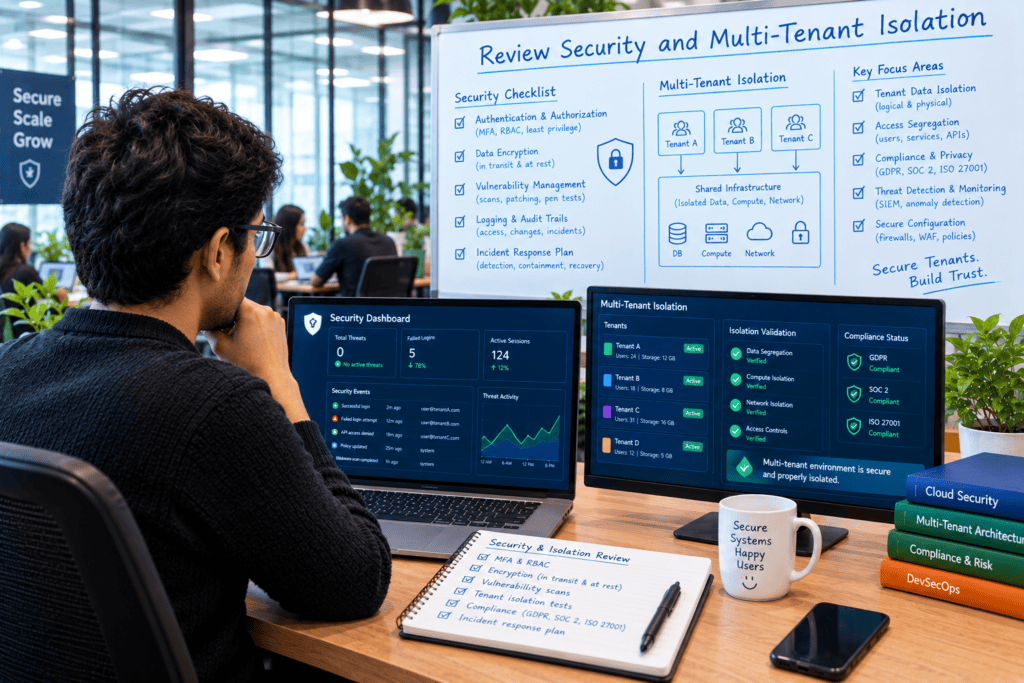
Scaling a SaaS product can increase the consequences of security mistakes.
Check:
- Authentication
- Authorization
- Tenant isolation
- Secrets management
- API access controls
- Encryption
- Dependency vulnerabilities
- Rate limiting
- Audit logging
- Administrative access
For multi-tenant applications, ask:
Can one customer consume enough shared resources to degrade service for everyone else?
This might be caused by
- significant exports,
- heavy API usage,
- expensive reports,
- file uploads,
- AI,
- background jobs,
- or large database queries.
Scaling is not only about supporting more users, but also about making sure that one component’s unsustainable load does not bring the rest to a halt, as well.
Test Backups and Recovery
A backup that has never been restored is not enough evidence of recovery readiness.
Check:
- Backup frequency
- Backup retention
- Backup storage
- Encryption
- Restoration procedure
- Restoration time
- Recovery point objectives
- Recovery time objectives
Run restoration tests where appropriate.
Also document who is responsible for recovery.
Technical scalability includes the ability to recover from failure, not just the ability to process more requests.
Model the Cost of Scaling
Infrastructure can scale technically while becoming financially impractical.
Estimate:
- Compute cost
- Database cost
- Storage
- CDN
- Bandwidth
- Monitoring
- Logging
- Queue processing
- Third-party APIs
- AI inference
- Backups
- Support and operations
Create at least three scenarios:
Current workload
What does the system cost today?
Expected workload
What happens at the next growth milestone?
Stress scenario
What happens during an unusually large traffic spike?
AWS’s guidance on architecture design explicitly requires factoring cost into decisions about design and using benchmarking and data to inform them.
The goal isn’t to predict the bill perfectly.
The goal is to avoid discovering that your growth strategy has multiplied infrastructure costs faster than revenue.
Run Realistic Scalability Tests
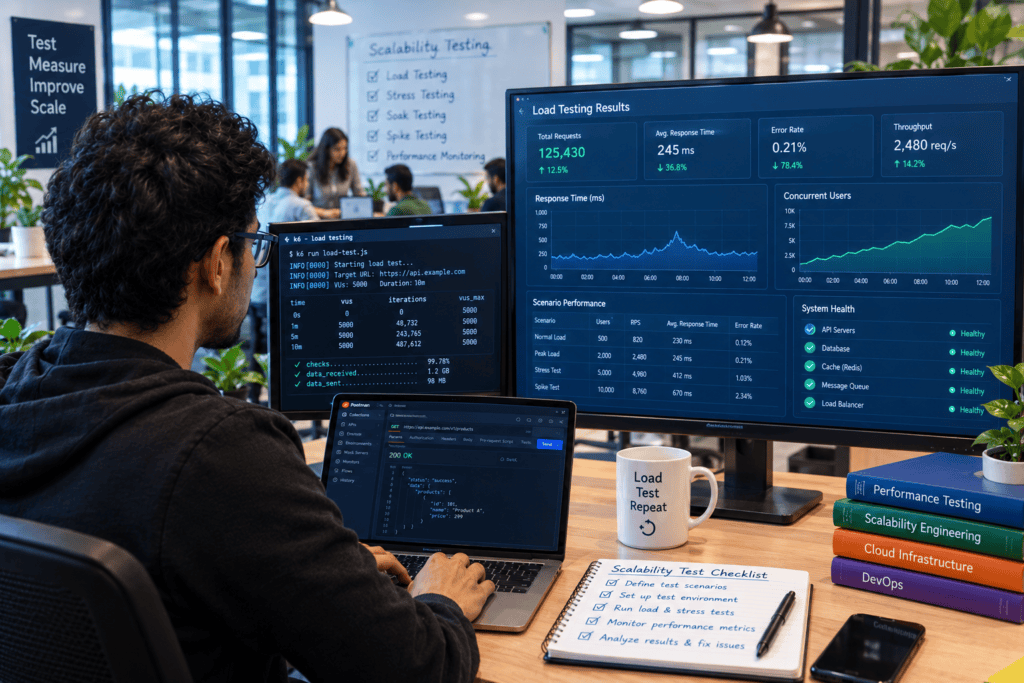
A scalability test should resemble actual usage.
Start with representative workflows.
For a SaaS product, that might include:
- User login
- Dashboard loading
- Creating a record
- Searching data
- Uploading a file
- Generating a report
- Sending a notification
- Calling an external API
Measure:
- Response time
- Throughput
- Error rate
- CPU
- Memory
- Database behavior
- Network utilization
- Queue depth
Test progressively rather than jumping immediately to an enormous number.
For example:
Baseline → normal load → expected peak → stress load
The key additions to KeyCDN’s recommendations for scaling-testing include following criteria, controlled environment, realistic scenario, load-testing, analysis, and re-testing after changes have been made.
However, the crucial addition is following to link the test results to specific architecture-related decisions.
Identify What Should Be Fixed Before Scaling
Not every technical problem needs to be solved before growth.
Usually worth addressing first (by addressability):
- data-loss risks (e.g security vulnerabilities)
- unbounded queries on database (e.g. security/availability risk)
- critical single points of failure (e.g. availability risk)
- backups that don’t work (data-loss risk)
- unsafe payments (data-loss/PCI risk)
- poor error handling (availability risk)
- unchecked background jobs (availability risk)
- performance problems due to bottlenecks (availability/performance risk)
- No rollback (deployments risk)
May be reasonable to defer:
- small code cleanups
- low-impact UX wins
- premature microservices
- complicated infrastructure for hypothetical traffic peaks
- advanced caching for systems that don’t have a bottleneck
- database sharding for systems which fit in a single db
This distinction helps to ensure that founders don’t waste time architecting solutions for problems that don’t yet exist.
When Should You Refactor Instead of Scaling?
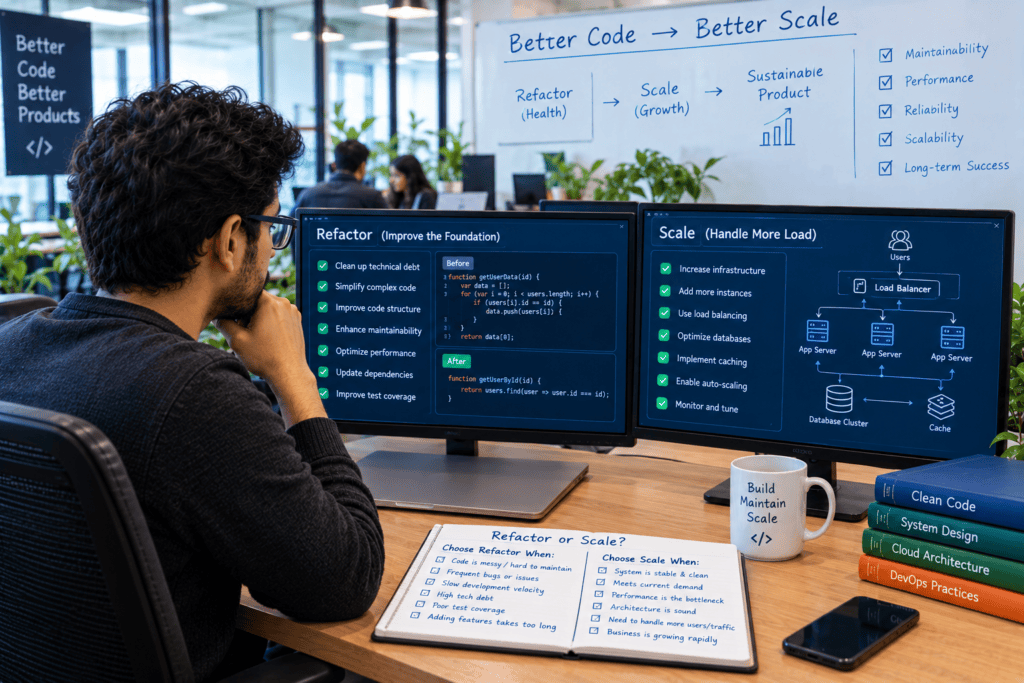
Consider rethinking your application design before adding more infrastructure capacity to these situations
Examples:
- Every request performs an expensive database query.
- A synchronous architecture has to wait for multiple external APIs
- One process is handling completely different workloads
- Background jobs run inside web requests.
- A single tenant can utilize all of the shared resources
- The application stores too much transient data in the database.
- Deployments require manual interventions
- A critical component has no fallback.
- Engineers can’t determine why requests are slow.
More servers would give you some headroom for now
A Simple Green, Yellow, Red Readiness Framework
Use this as a final review.
| Area | Green | Yellow | Red |
| Architecture | Bottlenecks documented | Some unclear dependencies | Critical single point of failure |
| Database | Queries measured and optimized | Some slow queries | Database regularly reaches limits |
| APIs | Limits/retries documented | Partial controls | Unbounded or unsafe operations |
| Jobs | Queue and workers monitored | Manual intervention required | Jobs regularly pile up |
| Infrastructure | Capacity thresholds defined | Mostly manual | No capacity visibility |
| Observability | Metrics, logs, traces | Partial visibility | Little production visibility |
| Deployment | Automated testing + rollback | Partial automation | Manual risky releases |
| Security | Access and isolation reviewed | Some gaps | Critical vulnerabilities |
| Recovery | Restore process tested | Documentation incomplete | Backups unverified |
| Cost | Growth scenarios modeled | Rough estimate | No idea of scale cost |
| Ownership | Clear technical owners | Shared responsibility | Nobody owns incidents |
If several critical areas are red, scaling infrastructure should probably not be the first action.
Investigate the underlying risks first.
What a Founder Should Ask Before Approving a Scaling Project
Non-technical founders don’t need to understand every implementation detail.
Ask the development team:
- What is the current bottleneck?
- What evidence proves it?
- What workload are we preparing for?
- Which component will fail first under that workload?
- What did the load test show?
- Can the application scale horizontally?
- What database changes are required?
- Which third-party APIs limit us?
- How are retries handled?
- What happens when a dependency goes down?
- How will we monitor the system after deployment?
- Can we roll back safely?
- What will the additional infrastructure cost?
- Which technical debt must be fixed now?
- Which improvements can wait?
- Who owns production incidents?
A good technical discussion should produce evidence and trade-offs, not just the statement:
“The system is scalable.”
How BkAbhi Fits Into the Development Lifecycle
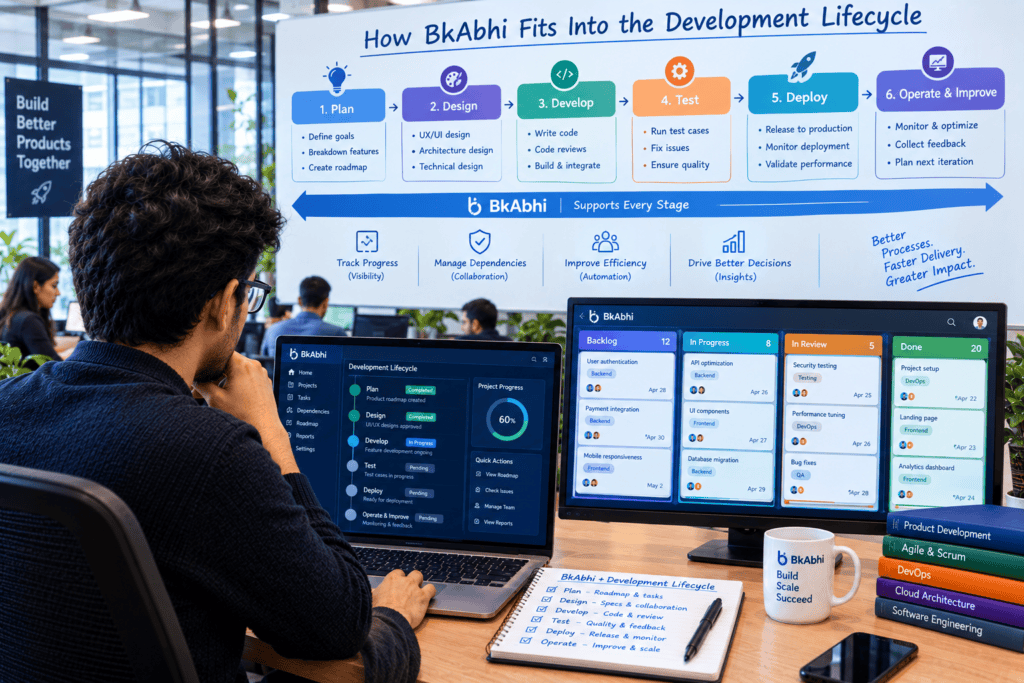
BkAbhi’s current public information lists scalable software architecture, SaaS application development, multi-tenant architecture, API development, cloud deployment, backend infrastructure, database architecture, performance optimization, AI integrations, and automation among its capabilities.
That makes these areas relevant when evaluating the technical foundation of a product before growth.
For a founder, however, the more useful question isn’t simply whether a development provider lists scalability as a service.
Ask what the engagement actually covers:
- Architecture review
- Bottleneck identification
- Database analysis
- Load testing
- Infrastructure changes
- API resilience
- Observability
- Deployment automation
- Security review
- Recovery planning
- Post-launch technical support
The exact scope, timeline, price, and technical implementation should be confirmed for the individual project rather than assumed from a general service description.
Final Pre-ScaleChecklist
Before ramping up capacity, make sure that:
Architecture
- critical paths are documented
- bottlenecks are known
- single points of failure are identified
- scaling strategy is defined
Database
- slow queries are measured
- indexes are reviewed
- connection limits are known
- storage growth is monitored
- backups are tested
APIs
- rate limits are understood
- timeouts are configured
- retries are controlled
- critical operations are idempotent
- pagination is implemented where needed
Background Processing
- long-running work is asynchronous where appropriate
- queues are monitored
- worker capacity is known
- failed jobs can be retried safely
Infrastructure
- capacity thresholds are defined
- autoscaling is configured where appropriate
- load balancing is tested
- health checks work correctly
Observability
- metrics exist
- logs are useful
- traces exist for critical workflows
- alerts are actionable
Deployment
- tests run automatically
- deployments are repeatable
- rollback is documented
- production changes can be monitored
Security
- authentication is reviewed
- authorization is enforced
- tenant isolation is tested
- secrets are protected
- rate limiting exists where necessary
Recovery
- backups are working
- restoration has been tested
- recovery responsibilities are documented
Cost
- current cost is known
- expected scale cost is estimated
- high-cost dependencies are identified
- AI/API usage is modeled where relevant
Team
- echnical ownership is clear
- runbooks exist
- incident procedures are documented
- someone is responsible for monitoring after launch
If several of the following critical areas are red, address the underlying constraints before assuming further infrastructure will solve them.
Conclusion
A technical scalability checklist before scaling should do more than confirm whether you can add another server.
The real objective is to understand how the system behaves as workload increases.
Start with the expected workload. Map the architecture. Identify the bottleneck. Review the database, APIs, queues, integrations, infrastructure and observability. Test realistic user journeys. Then decide whether the right response is optimization, vertical scaling, horizontal scaling, architectural refactoring, or simply waiting until the product has more evidence of demand.
The strongest scaling strategy is not the one with the most infrastructure.
It’s the one based on measured constraints, clear trade-offs, and an architecture that matches the workload you actually expect.
About the Author
Jeevesh Tripathi
Jeevesh Tripathi writes research-based content covering technology, AI, software, SaaS, and creator/business tools. His work focuses on practical comparisons, evidence-based evaluation, and explaining technical concepts in a way that founders and business readers can use.
For technology and software topics, the focus is on separating verified information from analysis, identifying meaningful trade-offs, and helping readers make decisions based on their own requirements.
Email: jeevesh@bkabhi.com